Replicating the Vision Transformer on the Terracotta Temples of Bishnupur
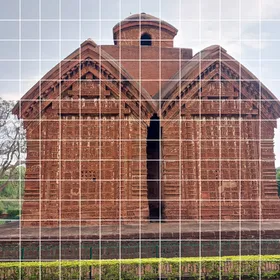
ViT-Base/16 in PyTorch on a 16GB M1, pointed at a hand-built dataset of ten Malla-era temples in eastern India. Trained from scratch it learned nothing; the same 85.8M parameters starting from ImageNet weights scored 88.9%.