papers-from-scratchSOTA architectures rebuilt in PyTorch
Three papers replicated tensor by tensor on Bengali data — no nn.Transformer, no nn.MultiheadAttention, no pre-built HuggingFace models.
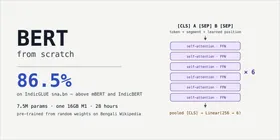
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding·Devlin et al., 2019
A 7.5M-parameter Bengali BERT, pre-trained from nothing on a laptop, that scores above published mBERT and IndicBERT on Bengali news classification.
- Params
- ~7.5M
- Corpus
- ~114MB
- Pre-trained
- ~28h
- Accuracy
- 86.5%
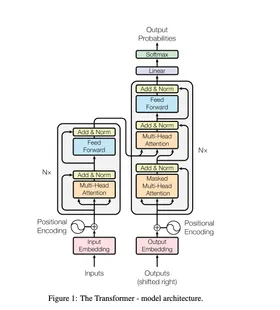
Attention Is All You Need·Vaswani et al., 2017
The original transformer rebuilt component by component, then trained to translate English into Bengali on one laptop.
- Params
- ~11M
- Paper
- ~65M
- Hardware
- M1, 16GB
- Data
- Samanantar
An Image Is Worth 16x16 Words·Dosovitskiy et al., 2021
A ViT trained on 1,935 photographs of Bengali terracotta temples — a dataset I had to build first — to test the paper's claim about pre-training. It failed, exactly as predicted.
- Images
- 1,935
- Classes
- 10
- From scratch
- 14.9%
- Pre-trained ViT-B/16
- 88.9%
All three in full→